Same day, two fixes: 5 days in one project, 175 in containerd
Part 4. The containerd fix finally merged. It isn't the fix I wrote, and two maintainers are the reason.
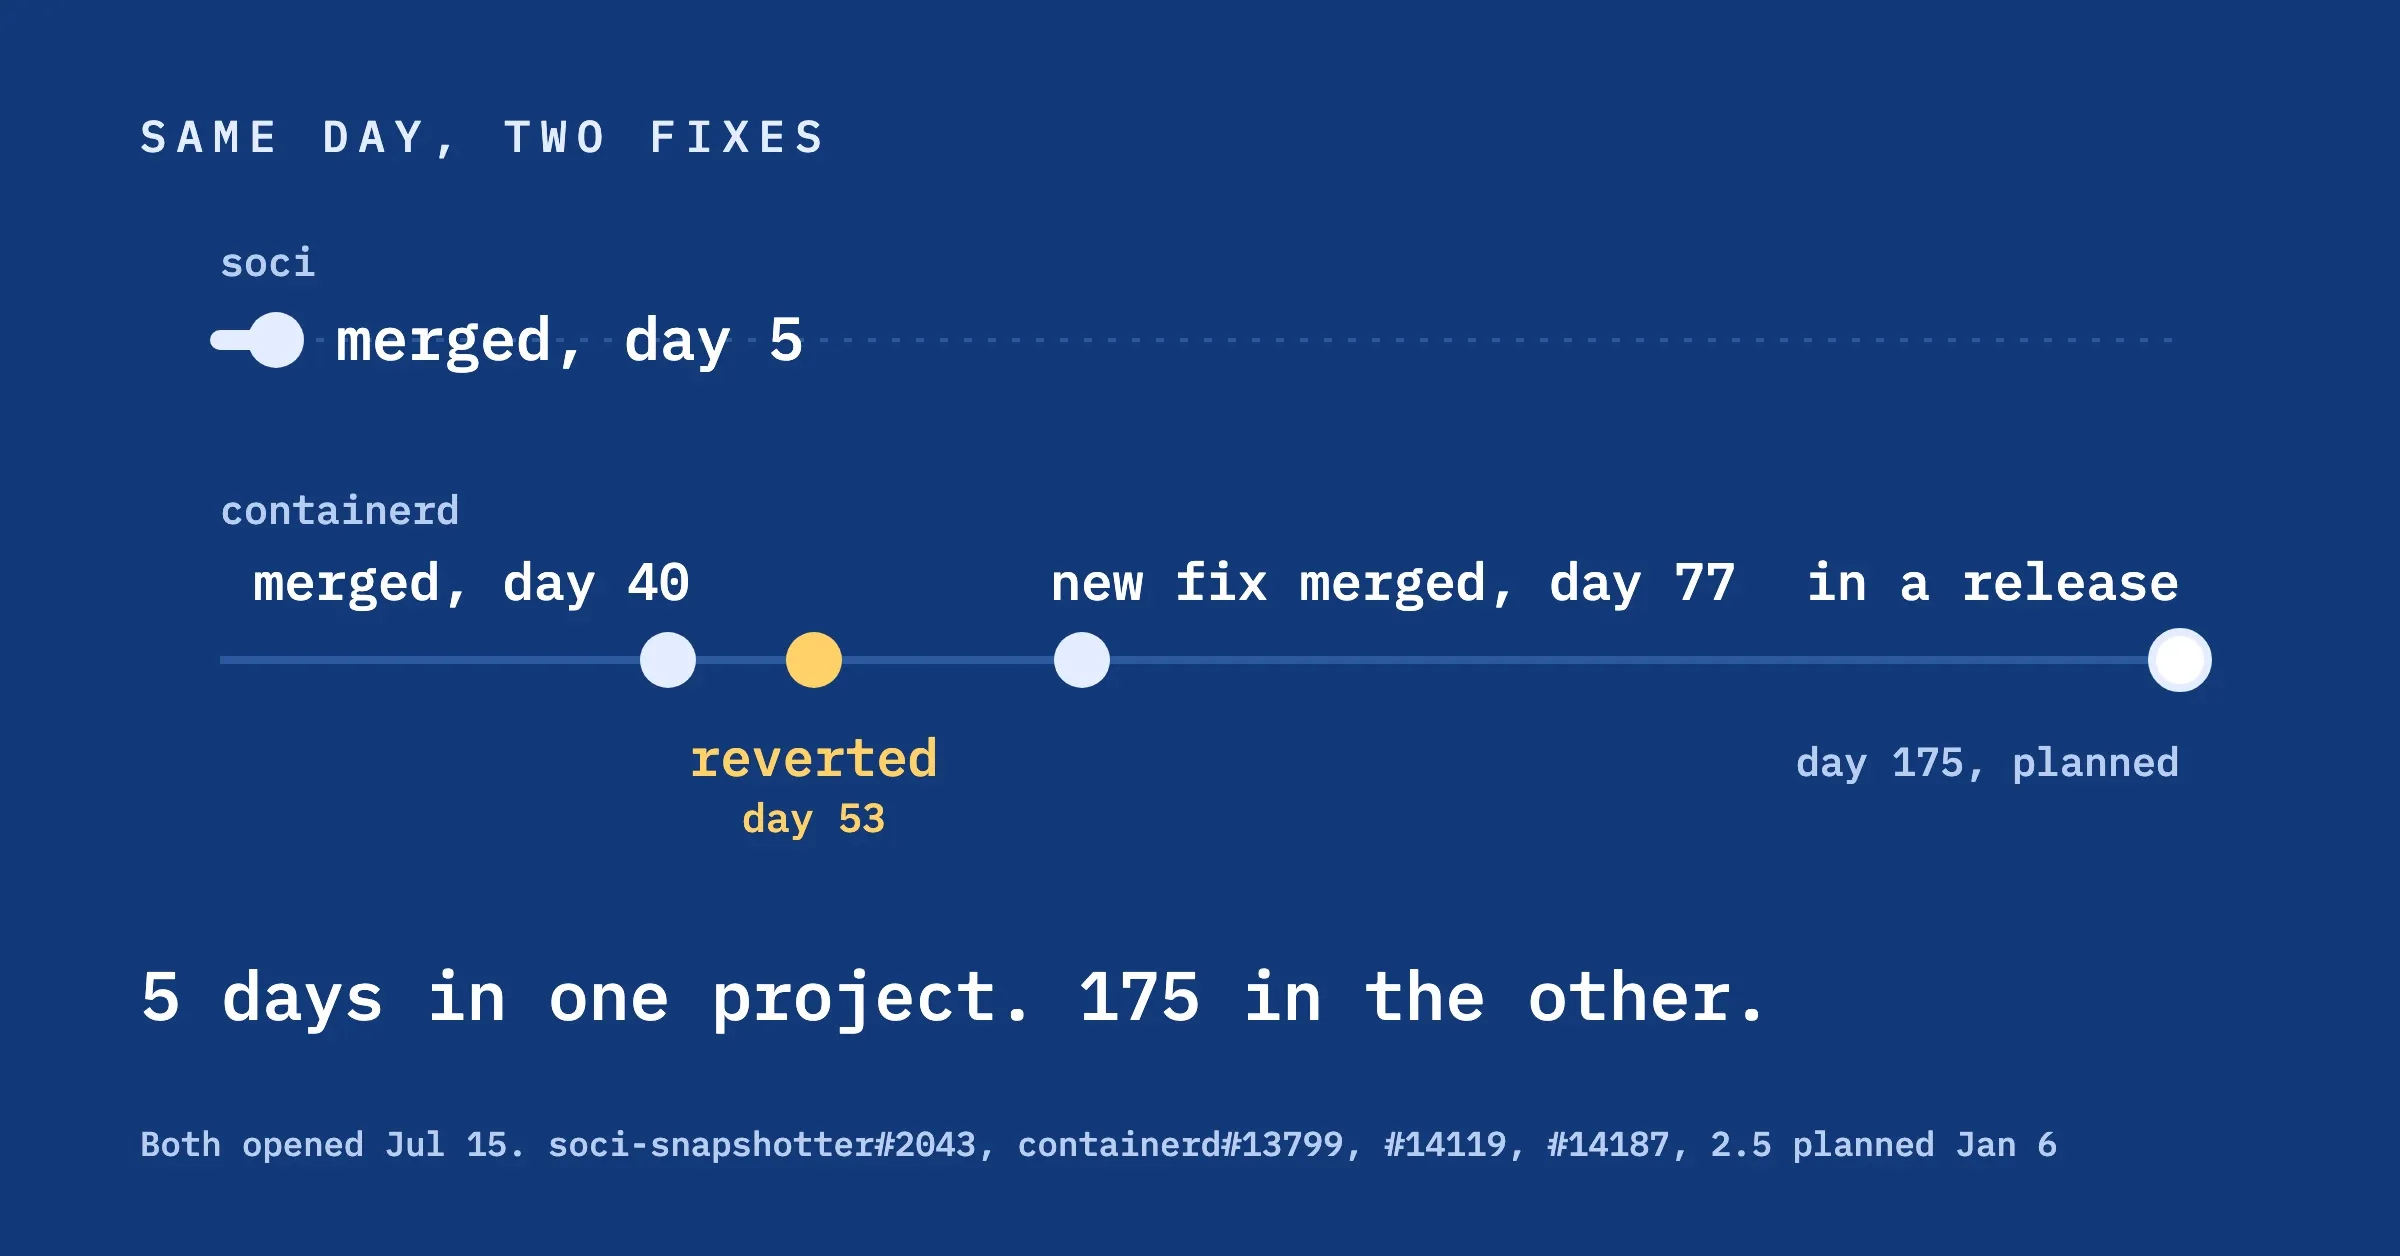
On July 15 I opened two pull requests for the same outage. The one to soci-snapshotter merged 5 days later. The one to containerd merged on day 40, got reverted on day 53, was replaced by a different fix that merged on day 77, and reaches a release on day 175, when containerd 2.5 ships on January 6. The fix that stays is better than mine. Fu Wei and Mike Brown argued me out of my own design to get there.
Five days, one answer
The soci bug had one right answer. Every file verified on first access opened a reader and never closed it, and the sibling function about 45 lines up closes the exact same reader. I showed the leak and added the close. The next day sondavidb wrote "LGTM pending CI, thanks for this!", ayush-panta approved, and on day 5 it was in. Nobody needed to argue about anything.
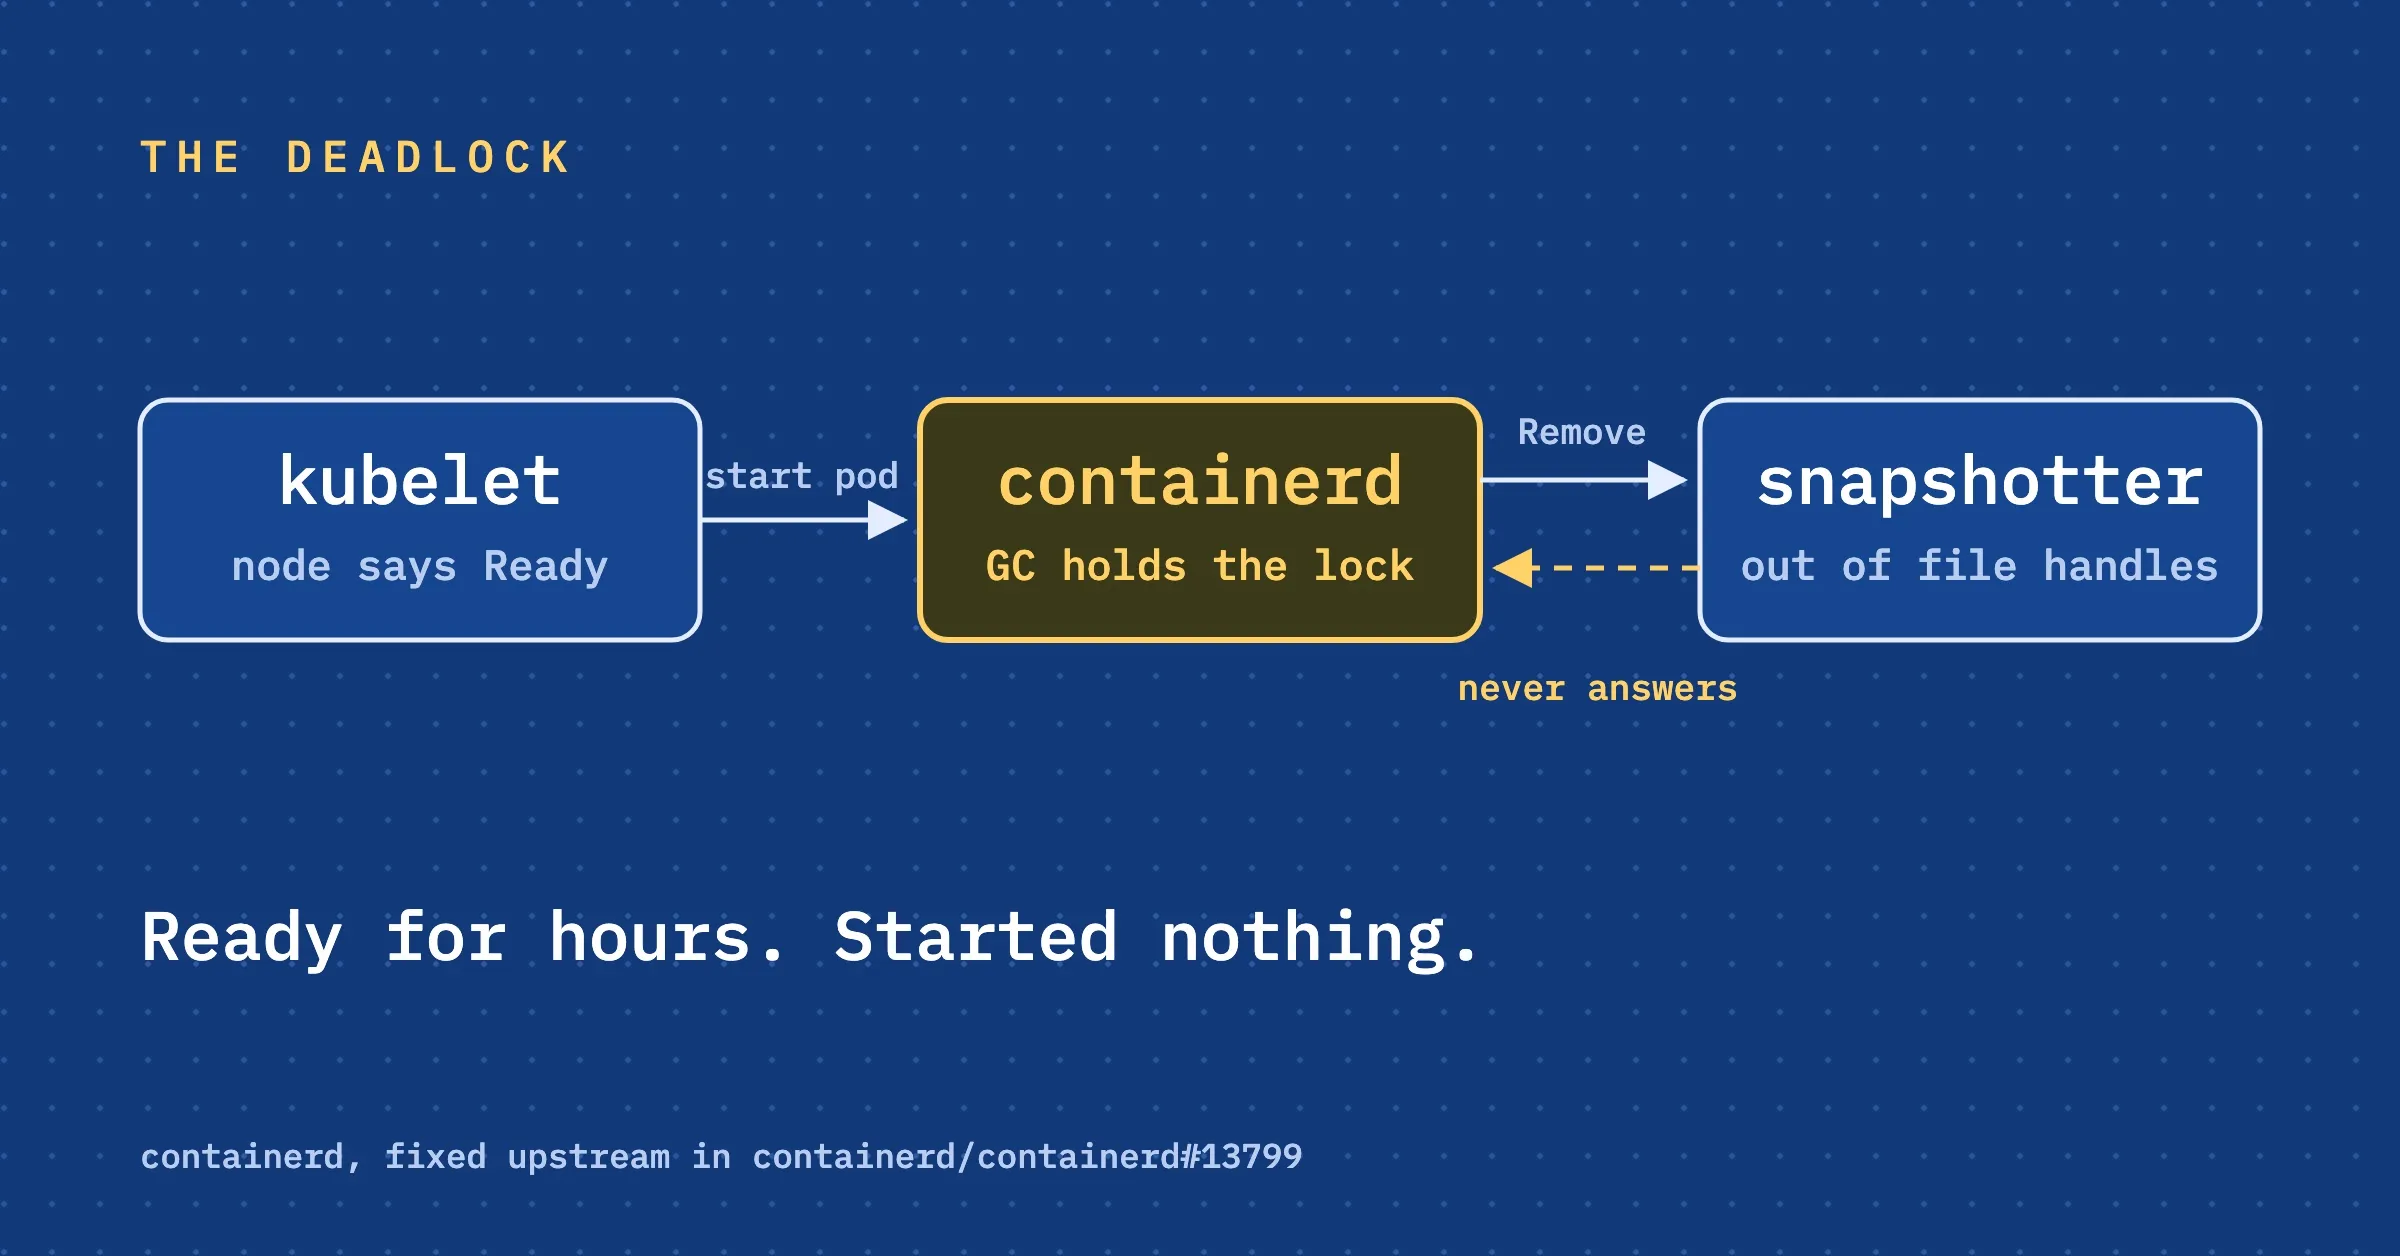
containerd was different. Snapshot garbage collection waited forever on a snapshotter plugin that had stopped answering, while it held a lock everything else on that snapshotter needed. A timeout fixes that. But where it goes, how long it is and what it breaks for thousands of clusters that never had my problem are questions with many plausible answers. That's what the review is for.
The thread where my fix moved
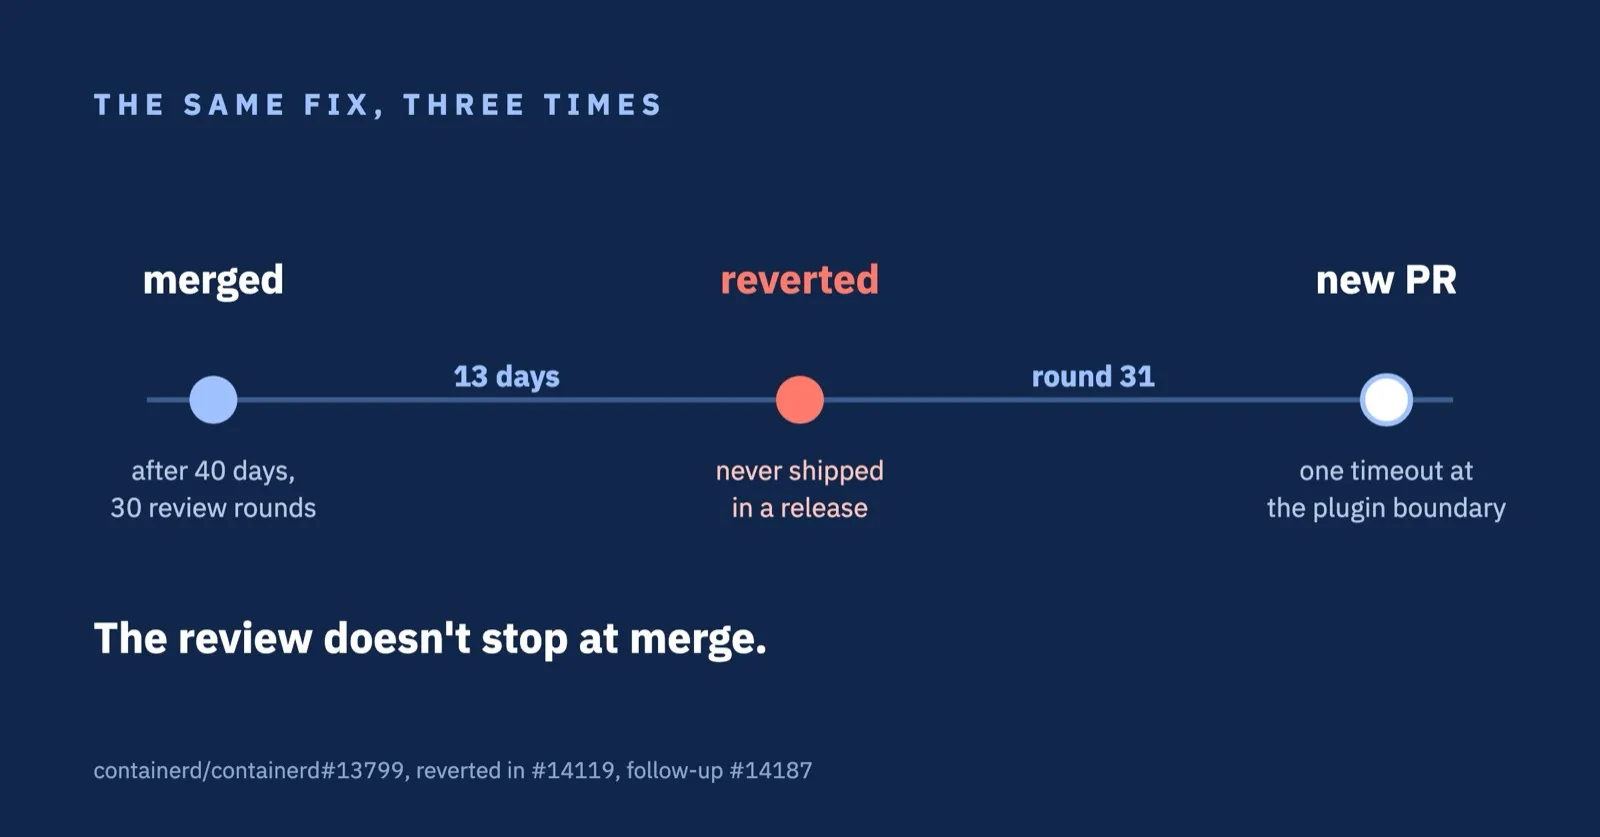
My 17-line timeout merged on day 40 after 30 review rounds. Mike merged it. That same evening I opened a follow-up, because my fix only bounded Remove, and GC also calls Walk and Cleanup while holding the lock.
Mike answered within hours with a pointer to a Slack discussion, and the next day I moved the timeout up a level as he suggested, with one setting instead of one per call, as Fu asked. Then a week of quiet, and a ping from me.
On September 2 Fu wrote the comment that moved the fix:
The proxy snapshotter is external process and it could happen deadlock anytime. I believe GC is just one of victims.
He proposed a default_timeout on the client containerd uses to talk to the plugin, so every call gets a deadline, not just the ones GC makes. Under half an hour later I wrote back: "makes sense to me, and it is the better home." Then I asked the awkward part out loud. My follow-up was already approved. Merge it anyway, or close it and go straight to the client?
Mike didn't sign off right away. He worried about the lock being held for the whole GC pass, and pointed out that a per-call timeout can't catch a pass where every call finishes just in time but the total is still too long. Fu answered with the GC code itself: the database-wide lock is released before the snapshotter cleanup runs, so a stuck plugin blocks only its own snapshotter. Mike came back the same day:
ah.. I see your reasoning now. Thanks! SGTM!
The revert
Three days later Fu wrote, "Since we are going to release 2.4, we need to address that or revert the timeout setting". Mike opened the revert that day, the same Mike who had merged my fix, with one line of explanation: "see agreement to go a different direction". My whole comment on it was:
The plot thinkens 😅 Agreed.
Typo included. A timeout in the wrong place, shipped in a release, is a setting nobody can take back. It merged the next day, 13 days after my fix landed, and containerd 2.4 shipped on September 16 without any fix. That one stung a little.
gantt
    dateFormat YYYY-MM-DD
    axisFormat %d %b
    todayMarker off
    section soci
    PR to merge :done, 2026-07-15, 2026-07-20
    section containerd
    first PR, 30 rounds :2026-07-15, 2026-08-24
    on main :crit, 2026-08-24, 2026-09-06
    the thread with Fu and Mike :2026-08-24, 2026-09-17
    new PR :2026-09-17, 2026-09-30
    waiting for 2.5 :2026-09-30, 2027-01-06
The red bar is the 13 days my first fix lived on main. The design that replaced it was settled in the bar under it, in a thread on a PR that never merged.
Thirteen days
I opened the replacement on September 17 and closed my follow-up with a note pointing at Fu's comment. One setting, default_timeout, gives every call containerd makes to a snapshotter plugin a deadline when the caller didn't bring one. It covers all 10 calls, not just the one that hurt me.
Fu's review had one real ask: "as it's core pkg, let's create new function name like NewSnapshotterWithOpts so that it's not breaking change to pkg user." The next day an automated review bot suggested the opposite, adding the option to the existing constructor. I did what Fu asked. Mike sent wording fixes for the docs and approved. Fu merged it on September 30, day 77.
The fastest containerd PR was the one where the arguing happened before the code. By the time I opened it, Fu had named the setting and Mike had agreed with the layer. The code just had to match. Next time anything touches a shared path, I'll open an issue with the incident and ask where the fix belongs before writing a line. It would have felt slower in July. It would have been faster by September.
If you run a proxy snapshotter
soci, stargz and nydus all run as proxy plugins. Once you're on containerd 2.5, this is the line to add:
[proxy_plugins.customsnapshot]
  type = "snapshot"
  address = "/var/run/mysnapshotter.sock"
  default_timeout = "30m"
The docs use 30m as the example. Pick something well above your slowest healthy call, because a call that hits it fails. Without it, a wedged plugin can hold its lock for good.
Where it stands
It's on main, not in a release. Until January I read every new issue that mentions snapshots/proxy with my stomach a little tight.
Part 3 ended with "not giving up". This one ends with: ask me again in January.
Credits and links
- Fu Wei (fuweid), for moving the fix to the right layer, the API catch and the merge
- Mike Brown (mikebrow), for the first merge, the hard questions, the revert and the docs
- sondavidb and ayush-panta at soci-snapshotter, for the 5 days
- awslabs/soci-snapshotter#2043
- containerd/containerd#13799, reverted in #14119
- containerd/containerd#14026, the thread where the fix moved
- containerd/containerd#14187, the fix that stays
- containerd PLUGINS.md and RELEASES.md
- Previous: part 3, reverted. The whole story: part 1
Nahum Litvin, Lead Platform Engineer.
Read next
containerd part 3: the fix got reverted
containerdA zero timeout in Go is not no timeout
containerd
References
- Original First published on LinkedIn
- PR · merged awslabs/soci-snapshotter#2043: fs/reader: fix spancache fd leak in file Verify
- PR · merged containerd/containerd#13799: metadata: bound snapshotter Remove during garbage collection
- PR · closed containerd/containerd#14026: metadata: bound each snapshot GC pass with a single timeout
- PR · merged containerd/containerd#14119: Revert "metadata: bound snapshotter Remove during garbage collection"
- PR · merged containerd/containerd#14187: snapshots/proxy: add optional default_timeout for proxy snapshotter calls
Comments